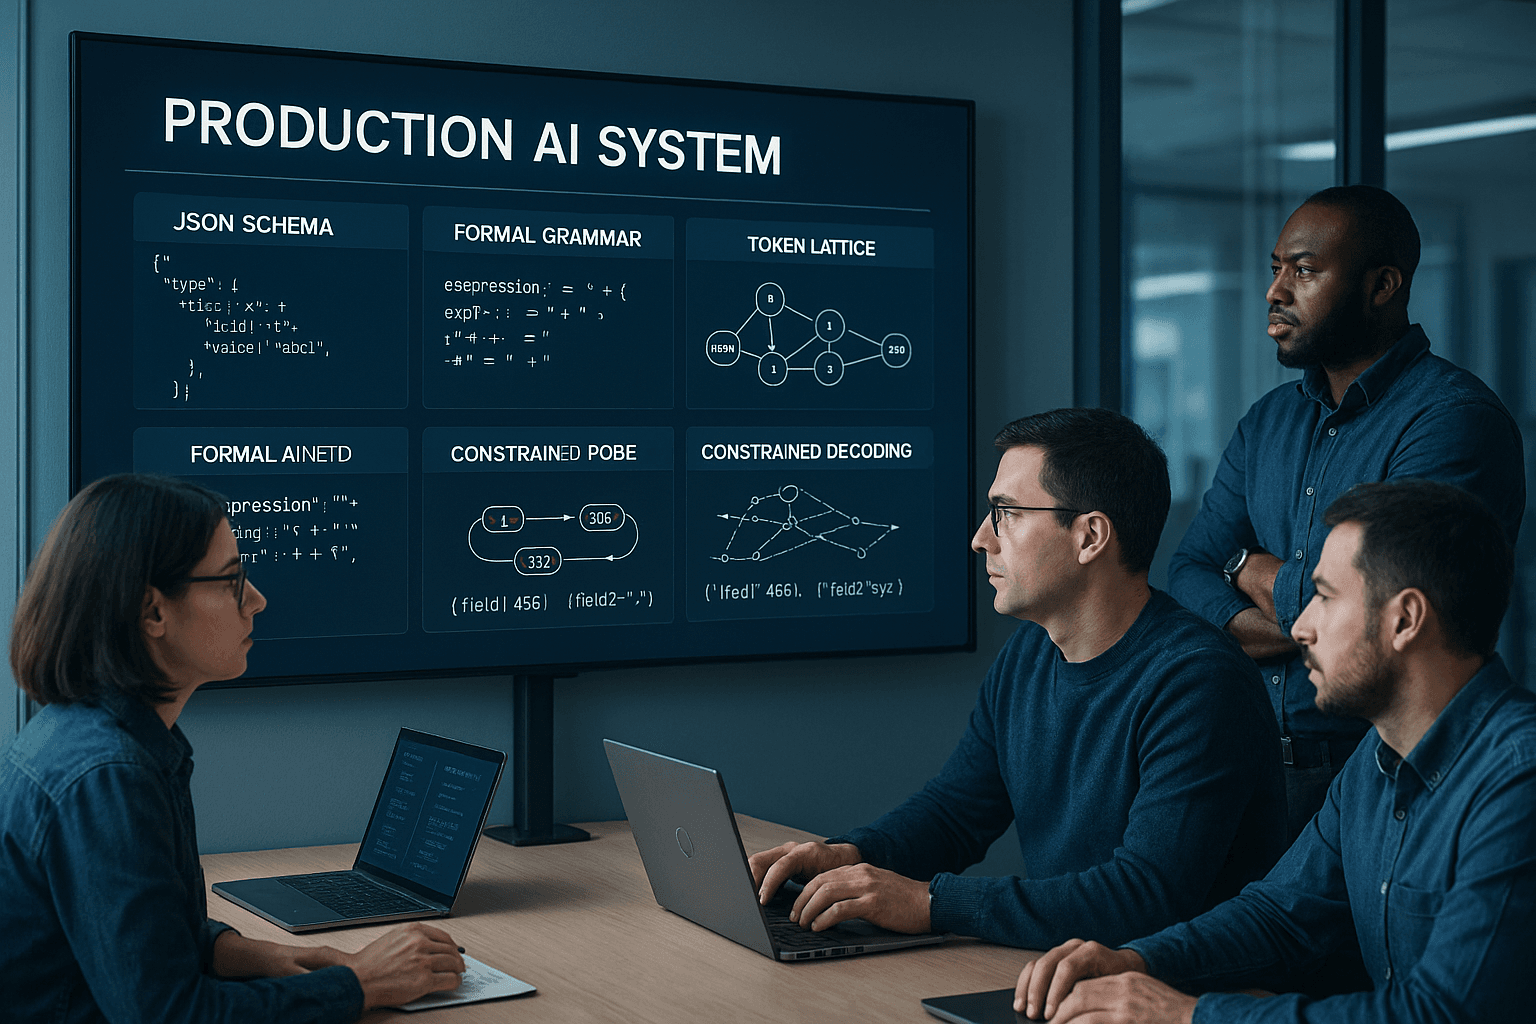
Constrained Decoding for Reliable Structured Output
How to enforce JSON schemas and grammars at generation time, with architecture patterns, evals, latency tradeoffs and failure modes.
GenAI Consulting24 min read
Practical guides, architecture notes, and lessons from shipping GenAI to production.
How to enforce JSON schemas and grammars at generation time, with architecture patterns, evals, latency tradeoffs and failure modes.
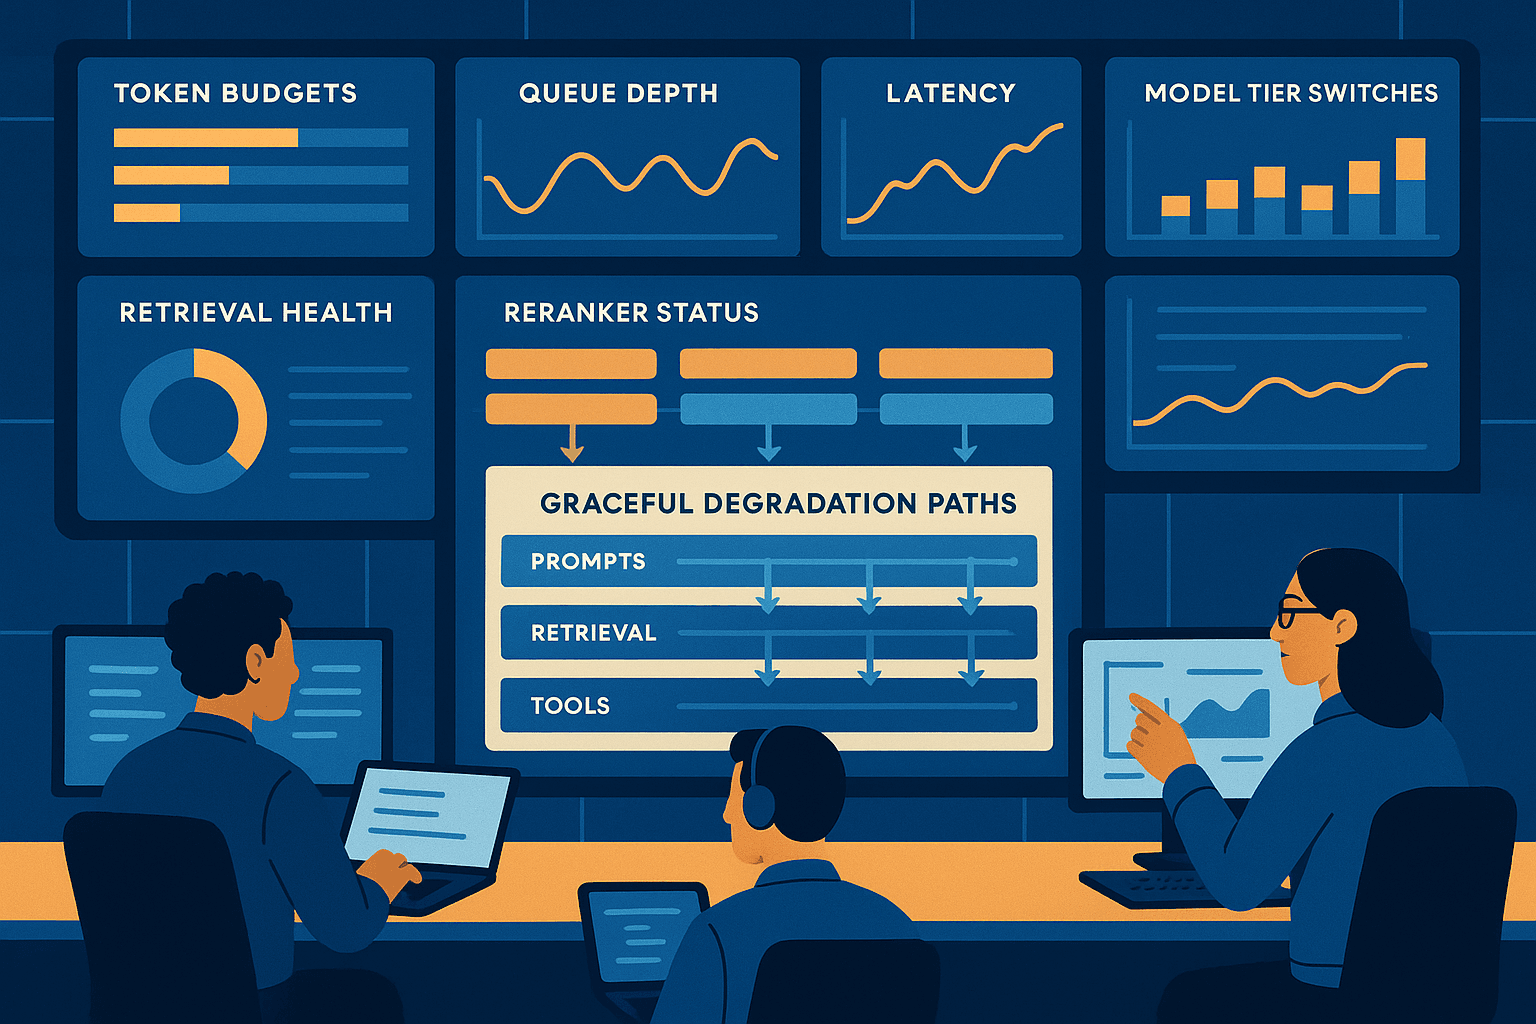
How to protect GenAI quality under token, queue and dependency pressure with degradation ladders, admission control, evals and rollout.
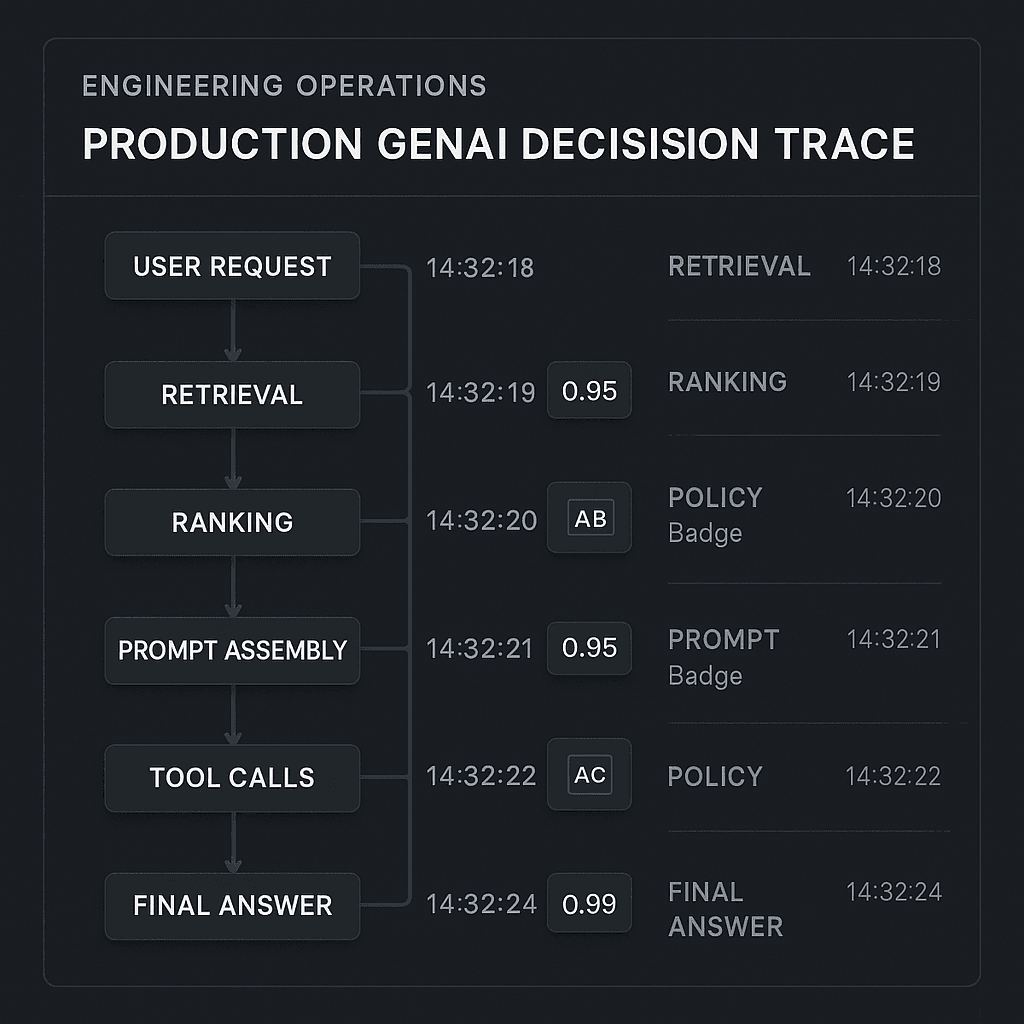
How to design decision logs that reconstruct why a system answered, abstained, routed, called a tool or triggered a guardrail.
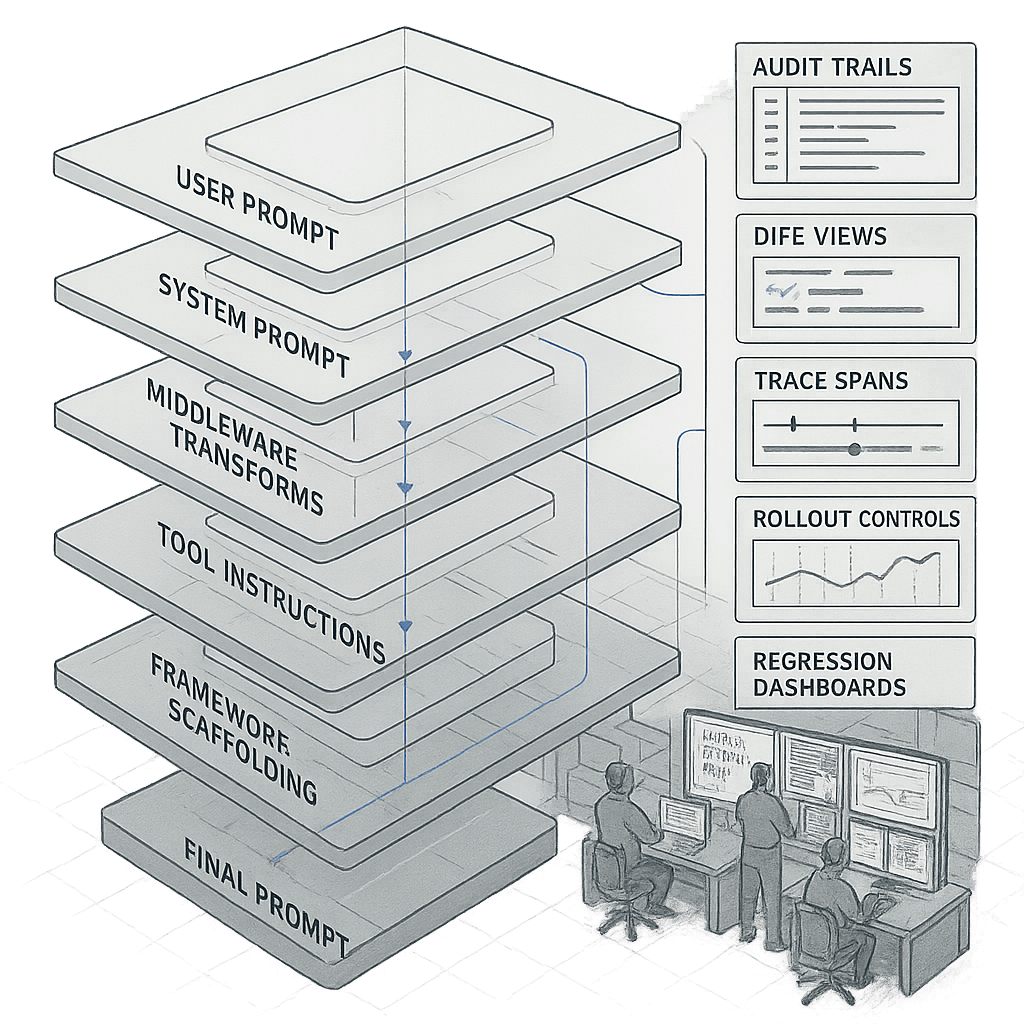
How to make system prompts, middleware, tool instructions and framework scaffolding observable to prevent silent prompt drift in production.
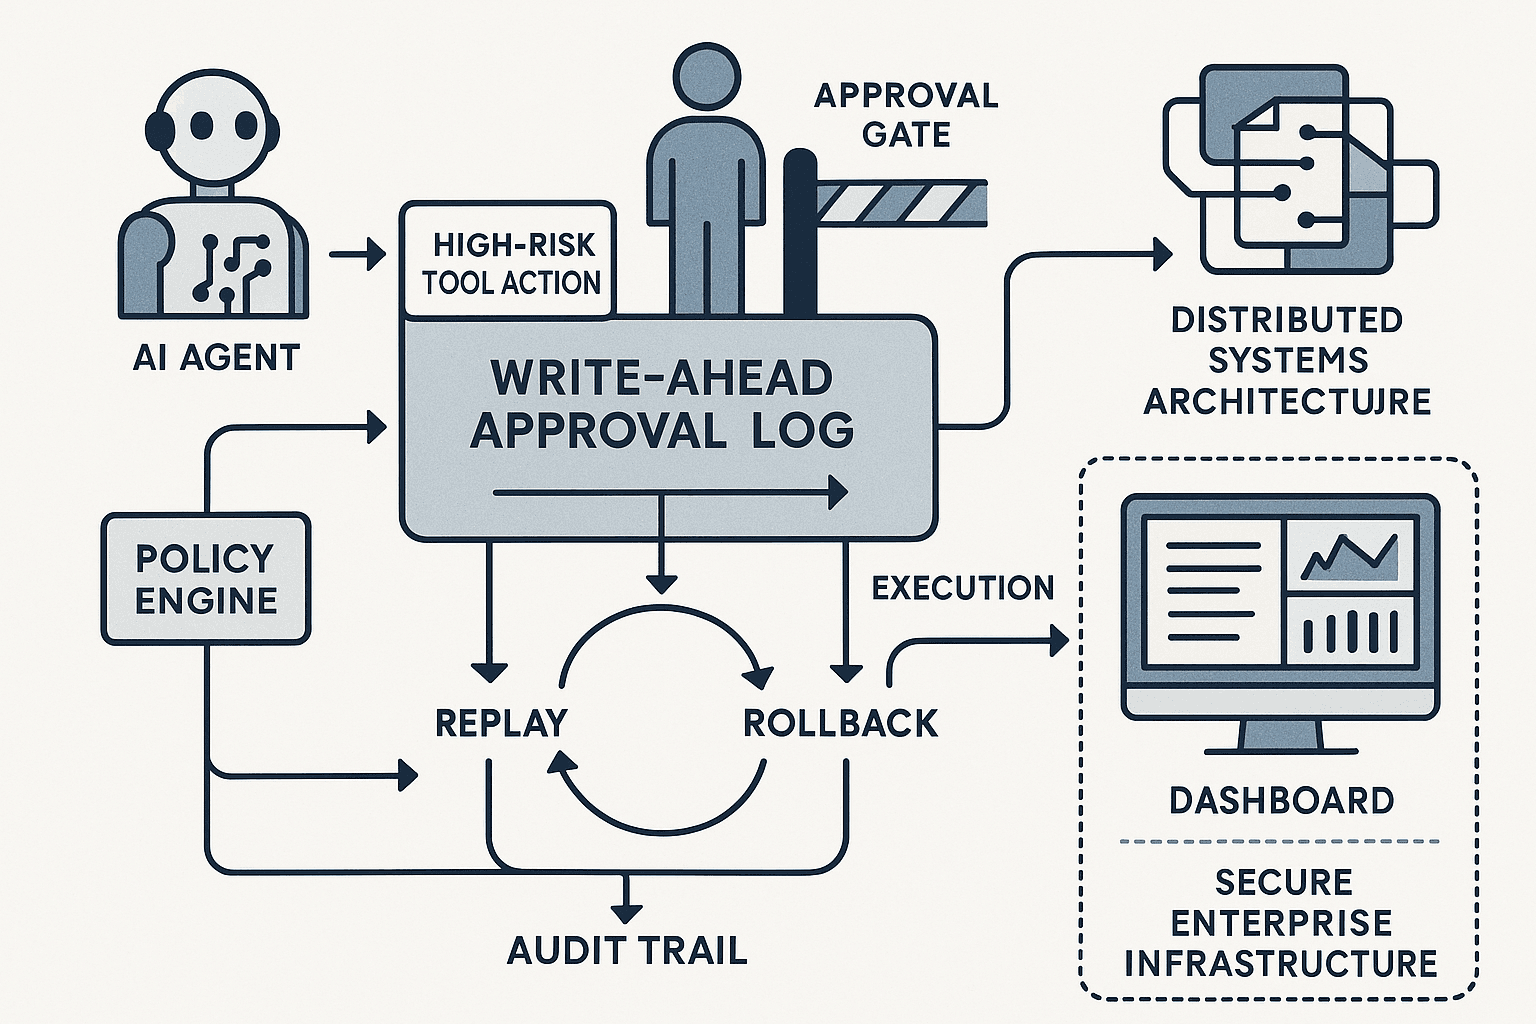
How write-ahead approval logs control high-risk agent actions, with support for review, replay, cancellation, auditability and rollback.
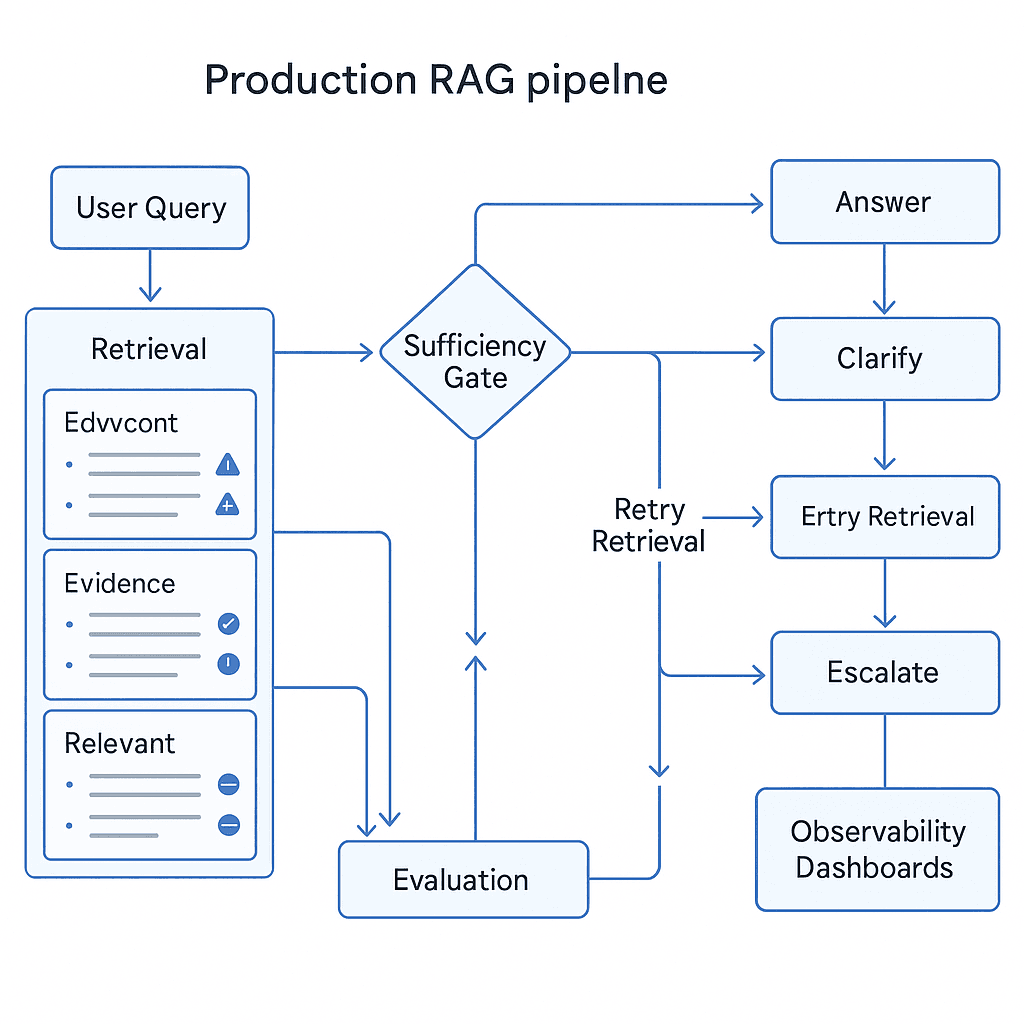
How to add a sufficiency gate to RAG that detects weak context, picks the right next action and reduces hallucinations before answering.
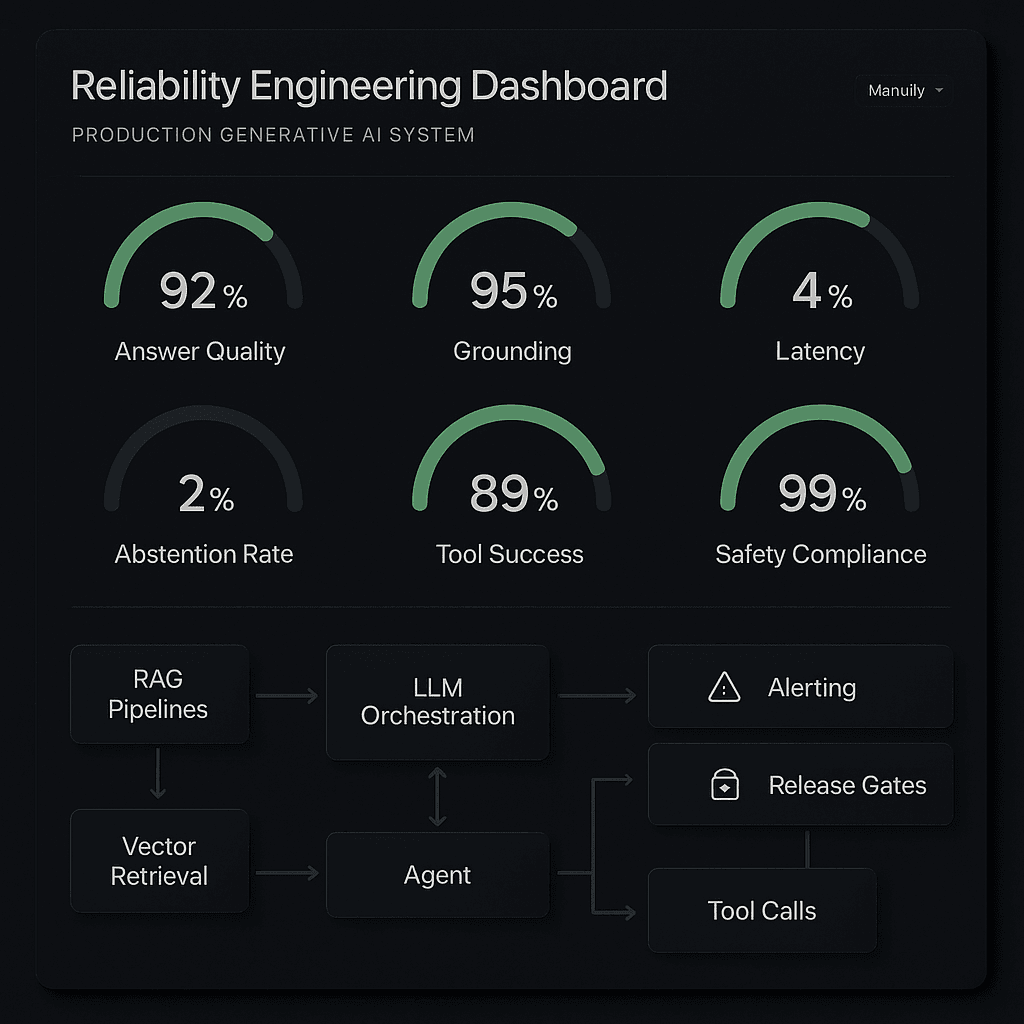
How to define GenAI SLOs beyond uptime, covering quality, grounding, latency, abstention, tool success, cost and safety, plus budgets and alerts.
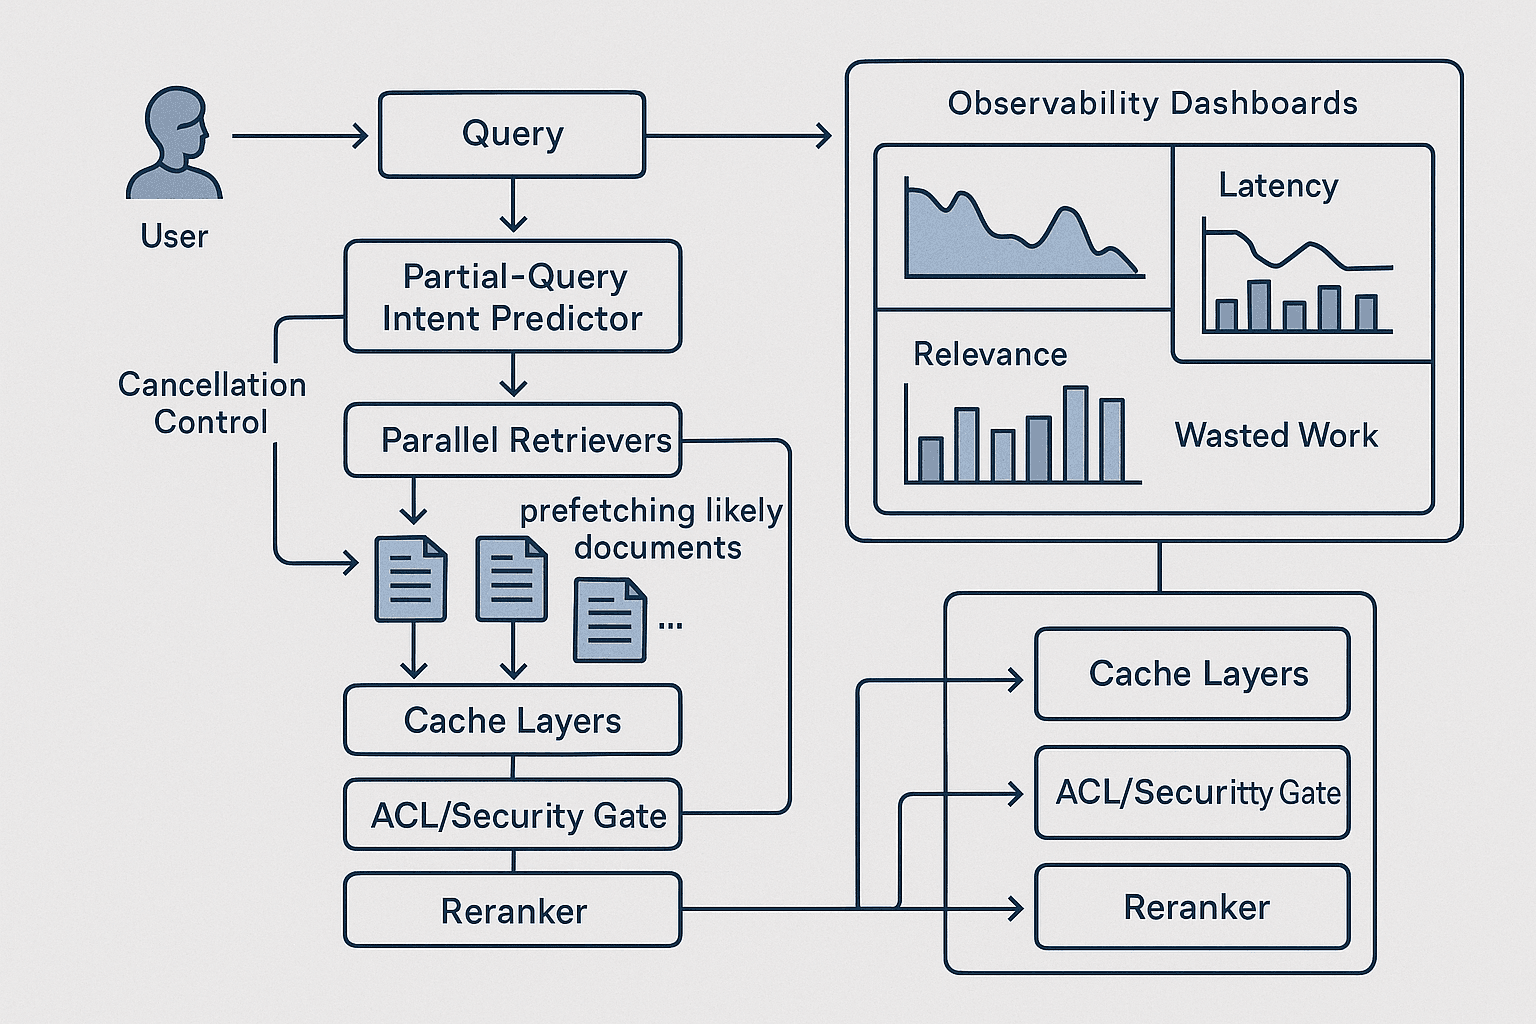
How speculative retrieval hides search latency in RAG using intent prediction, prefetch and cancellation, with ACL safety, evals and cost tradeoffs.
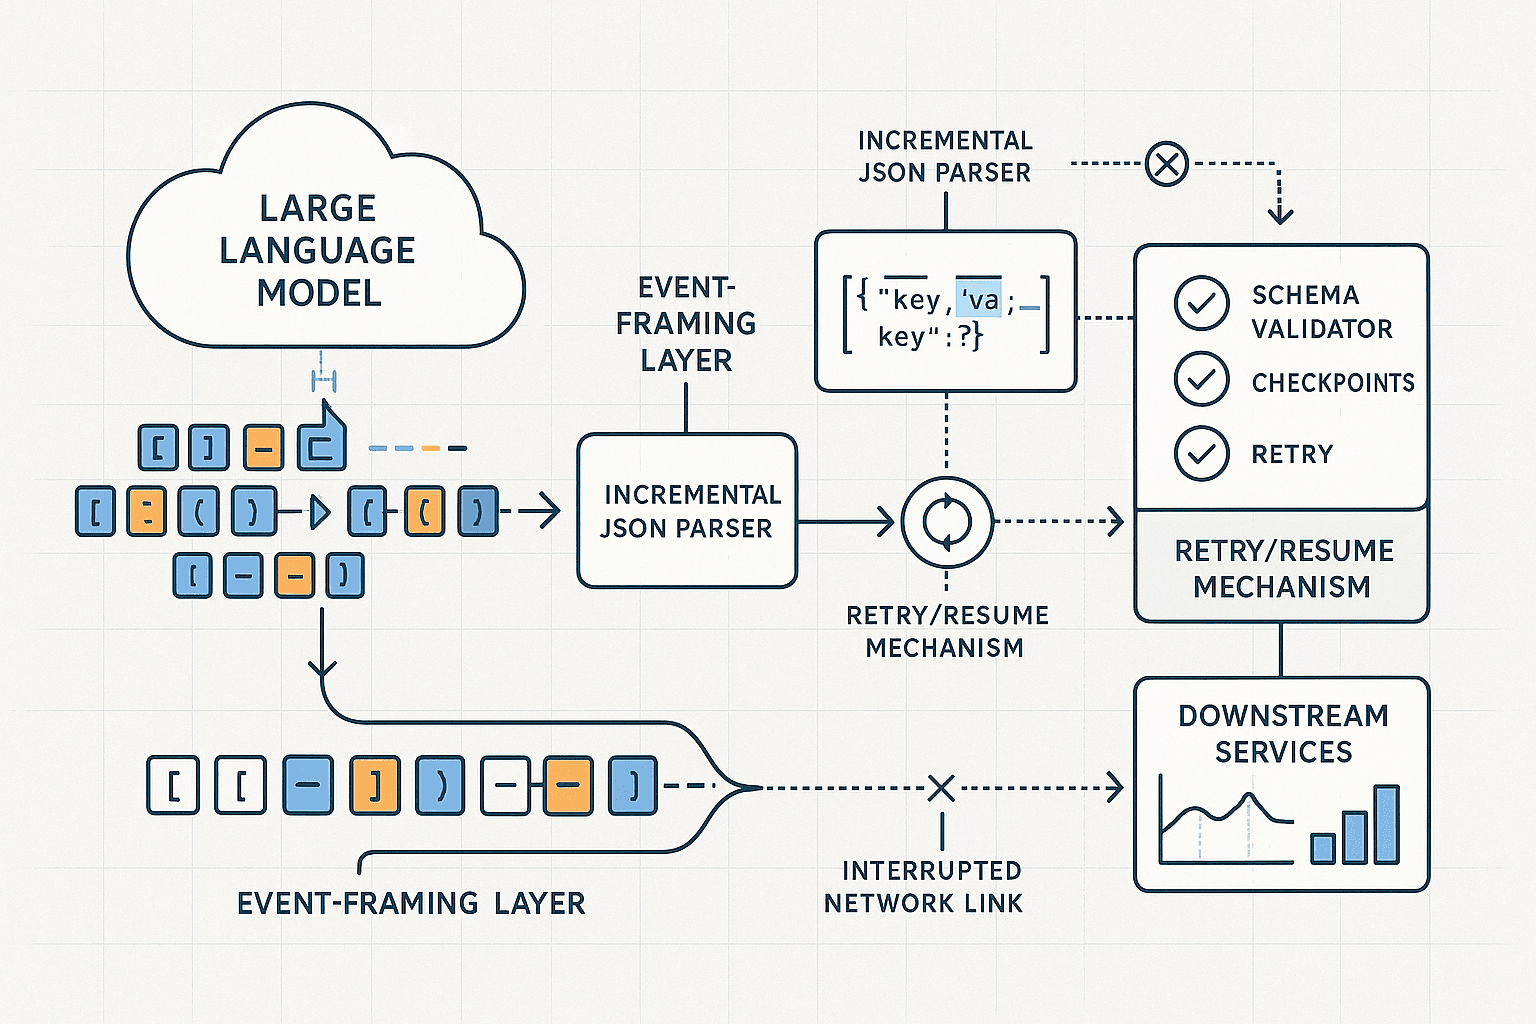
How to stream structured JSON from LLMs despite truncation, retries, schema drift and disconnects, with architecture, evals and observability.
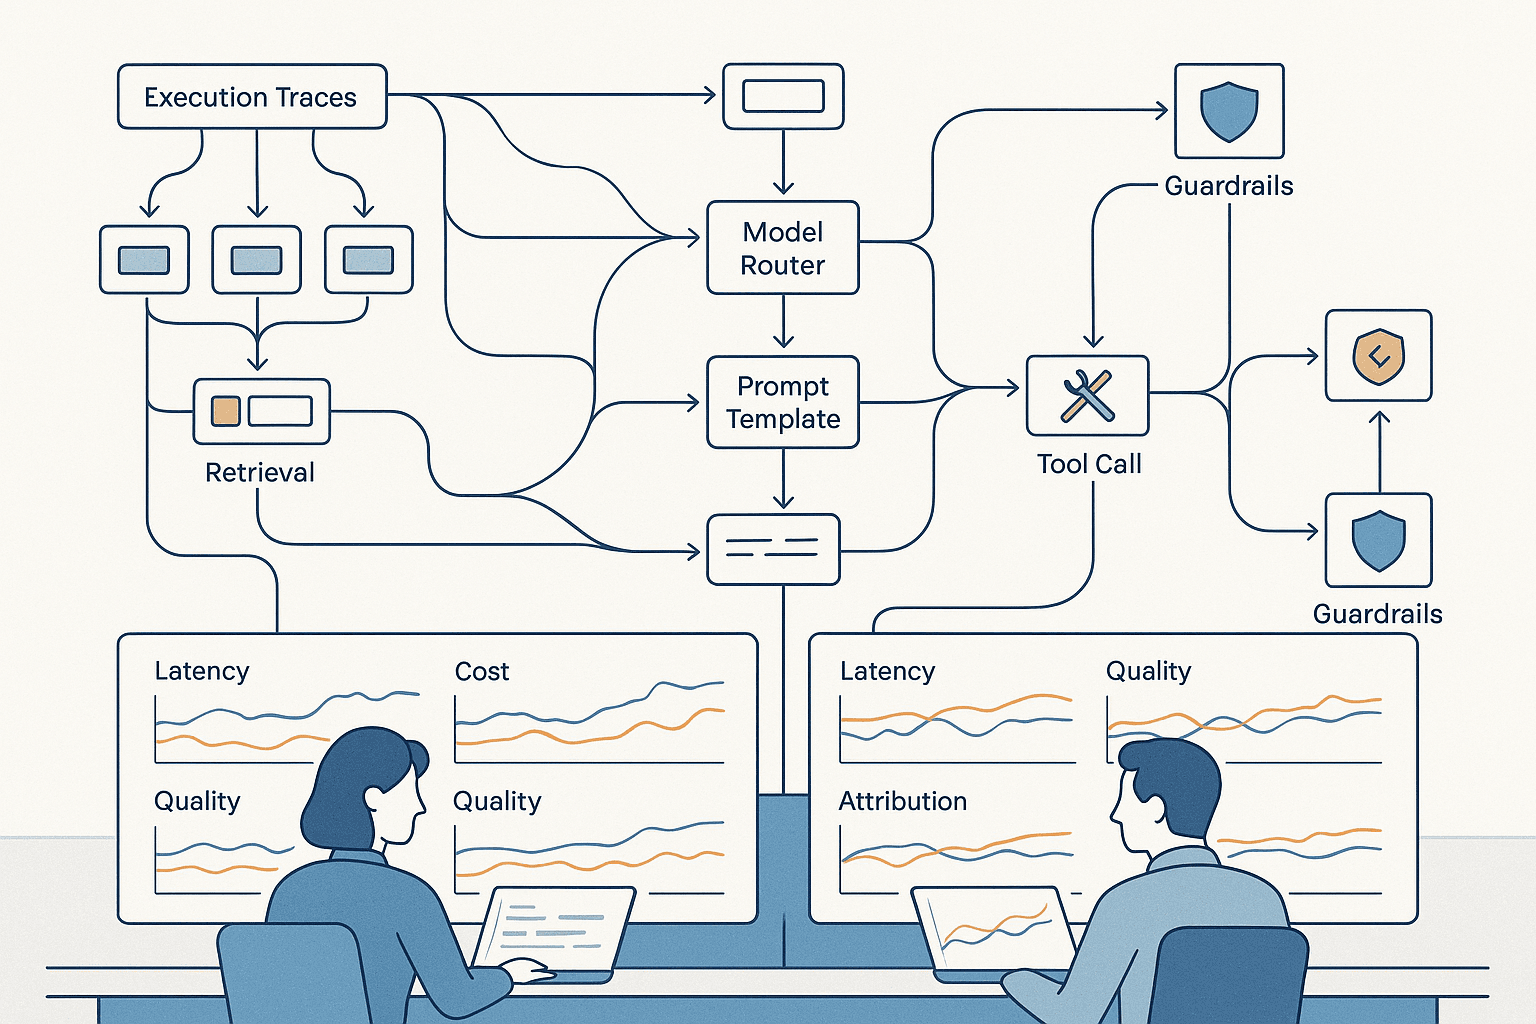
How to isolate the causal impact of retrieval, routing, prompt, tool policy and guardrail changes on outcomes in GenAI systems.
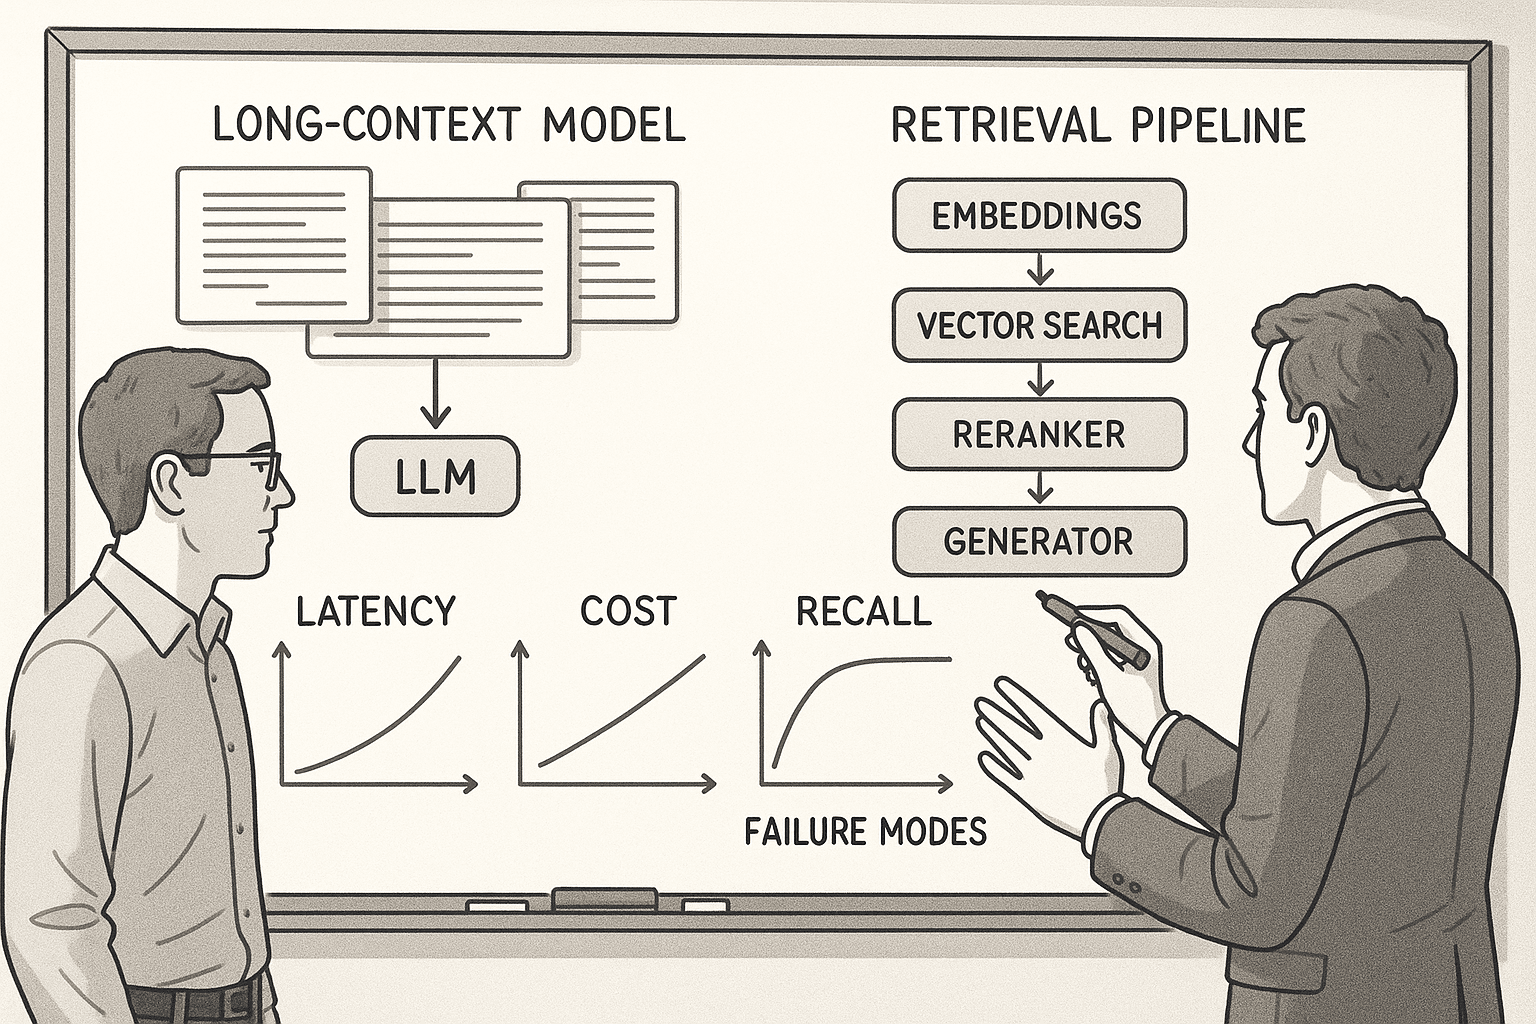
A framework for deciding when long-context models beat RAG, when retrieval wins, and how to evaluate hybrids under real cost and latency.
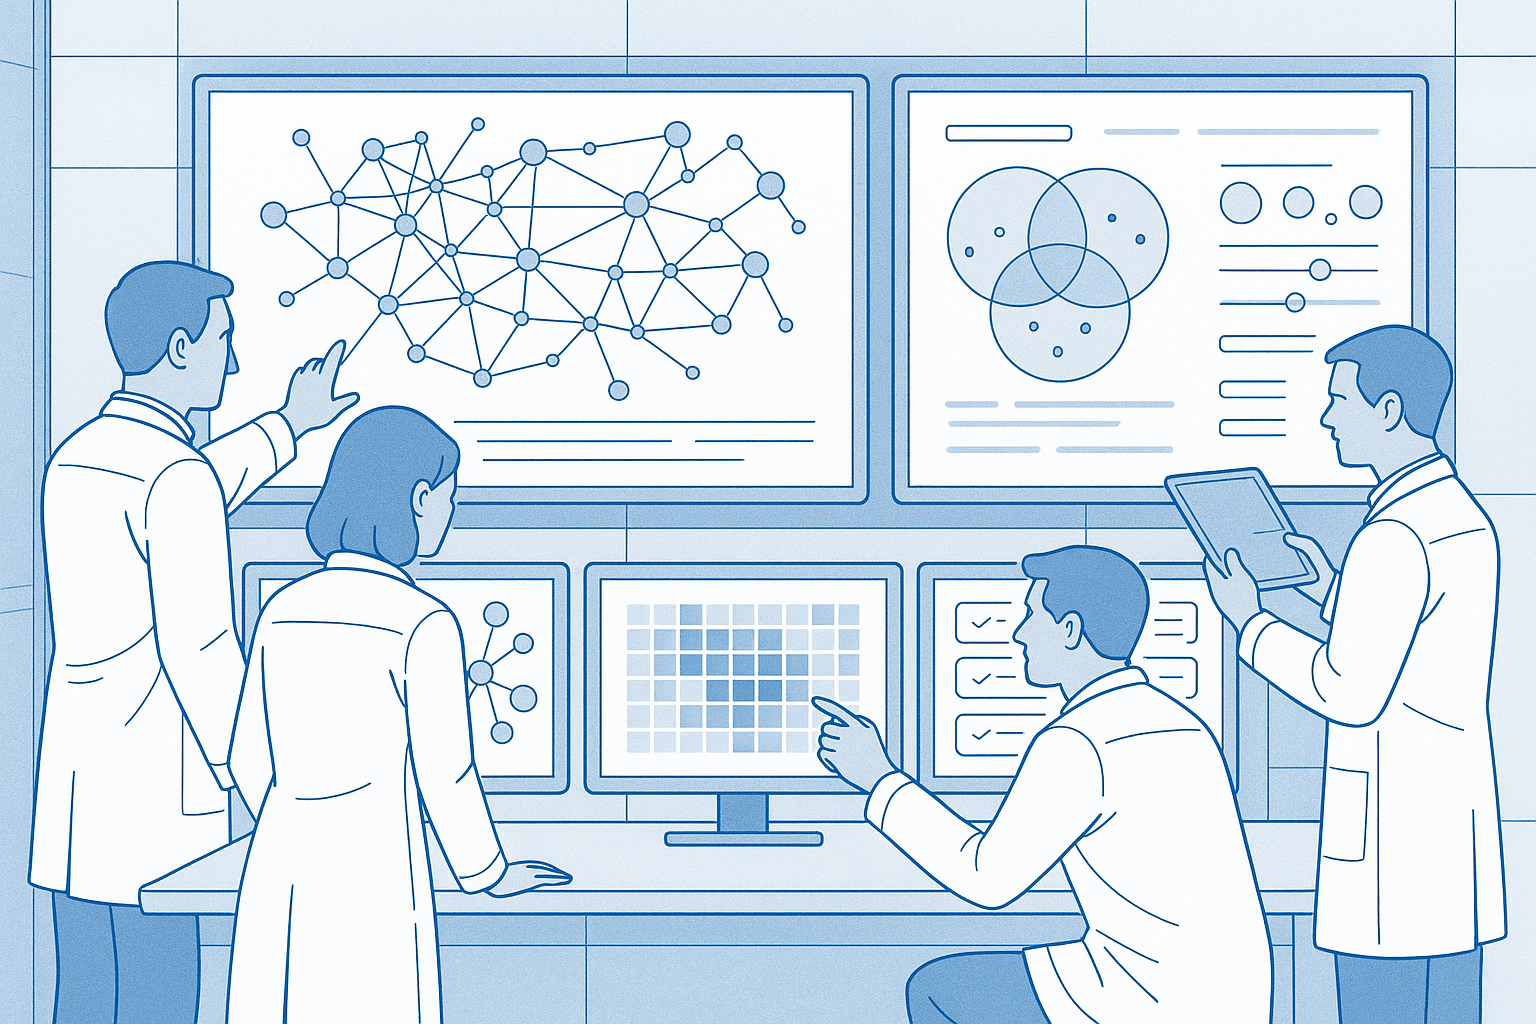
How to test whether your corpus can answer expected queries, and find corpus gaps, metadata blind spots and unanswerable query classes.